Detect retrieval regressions
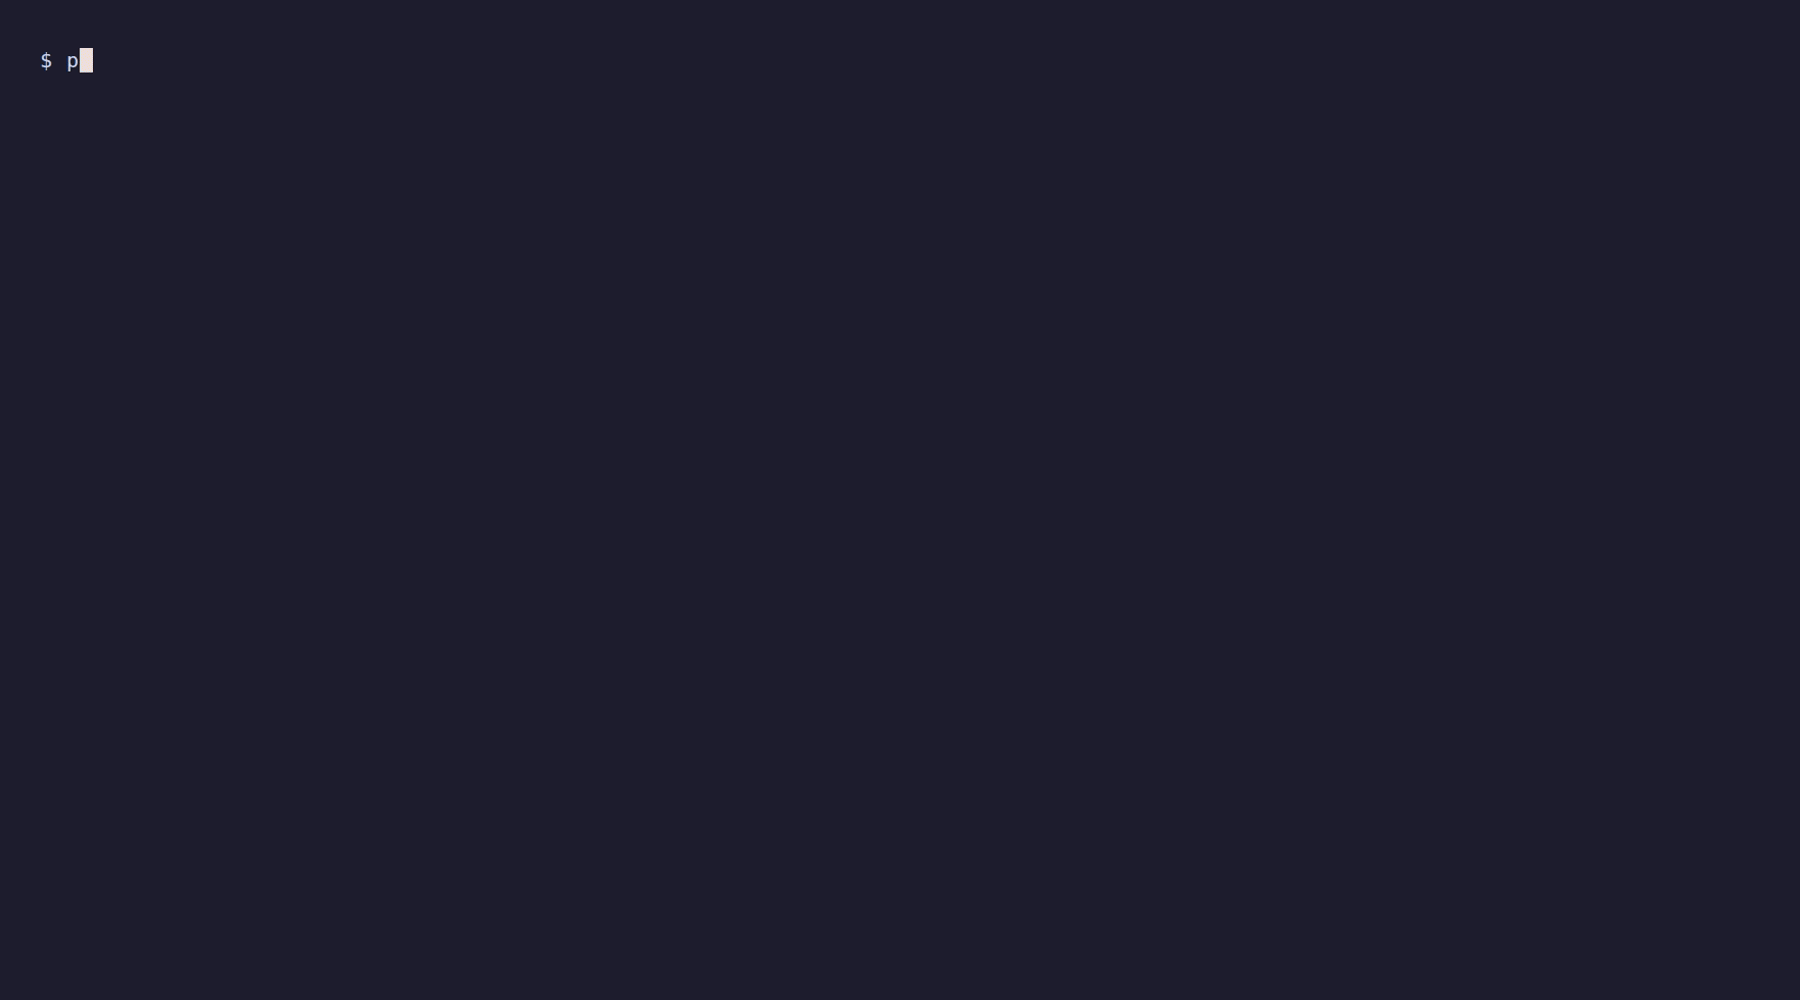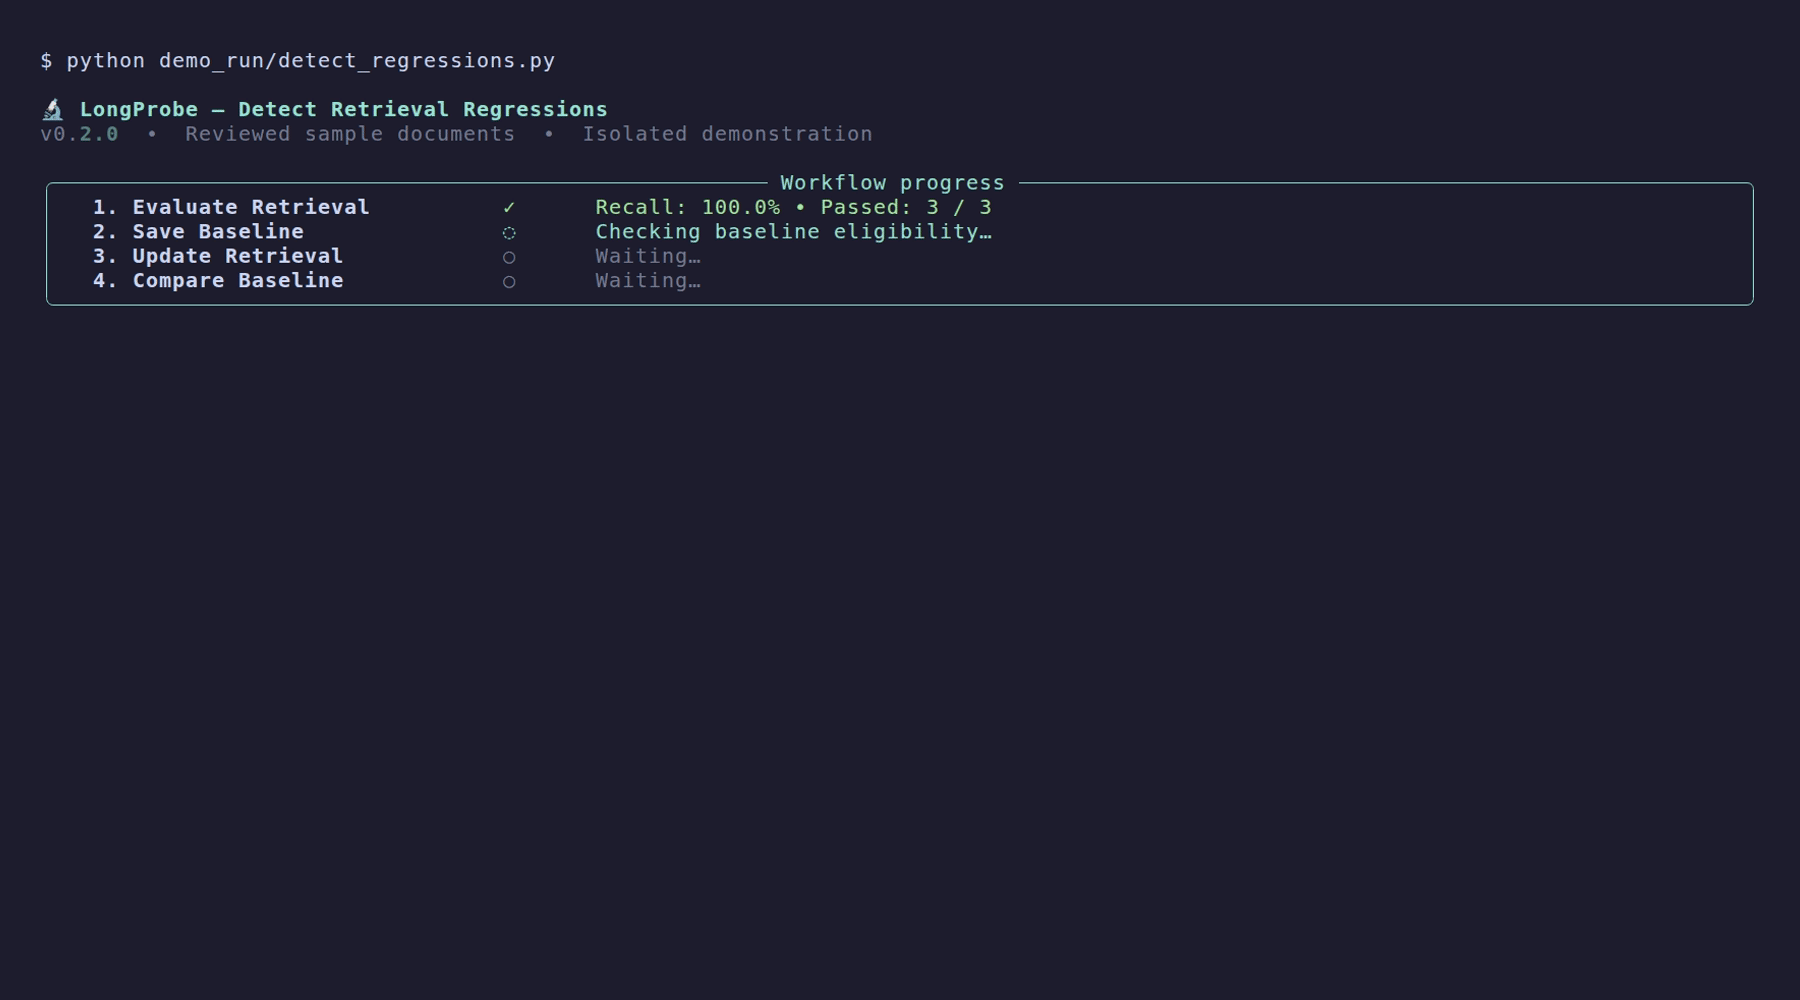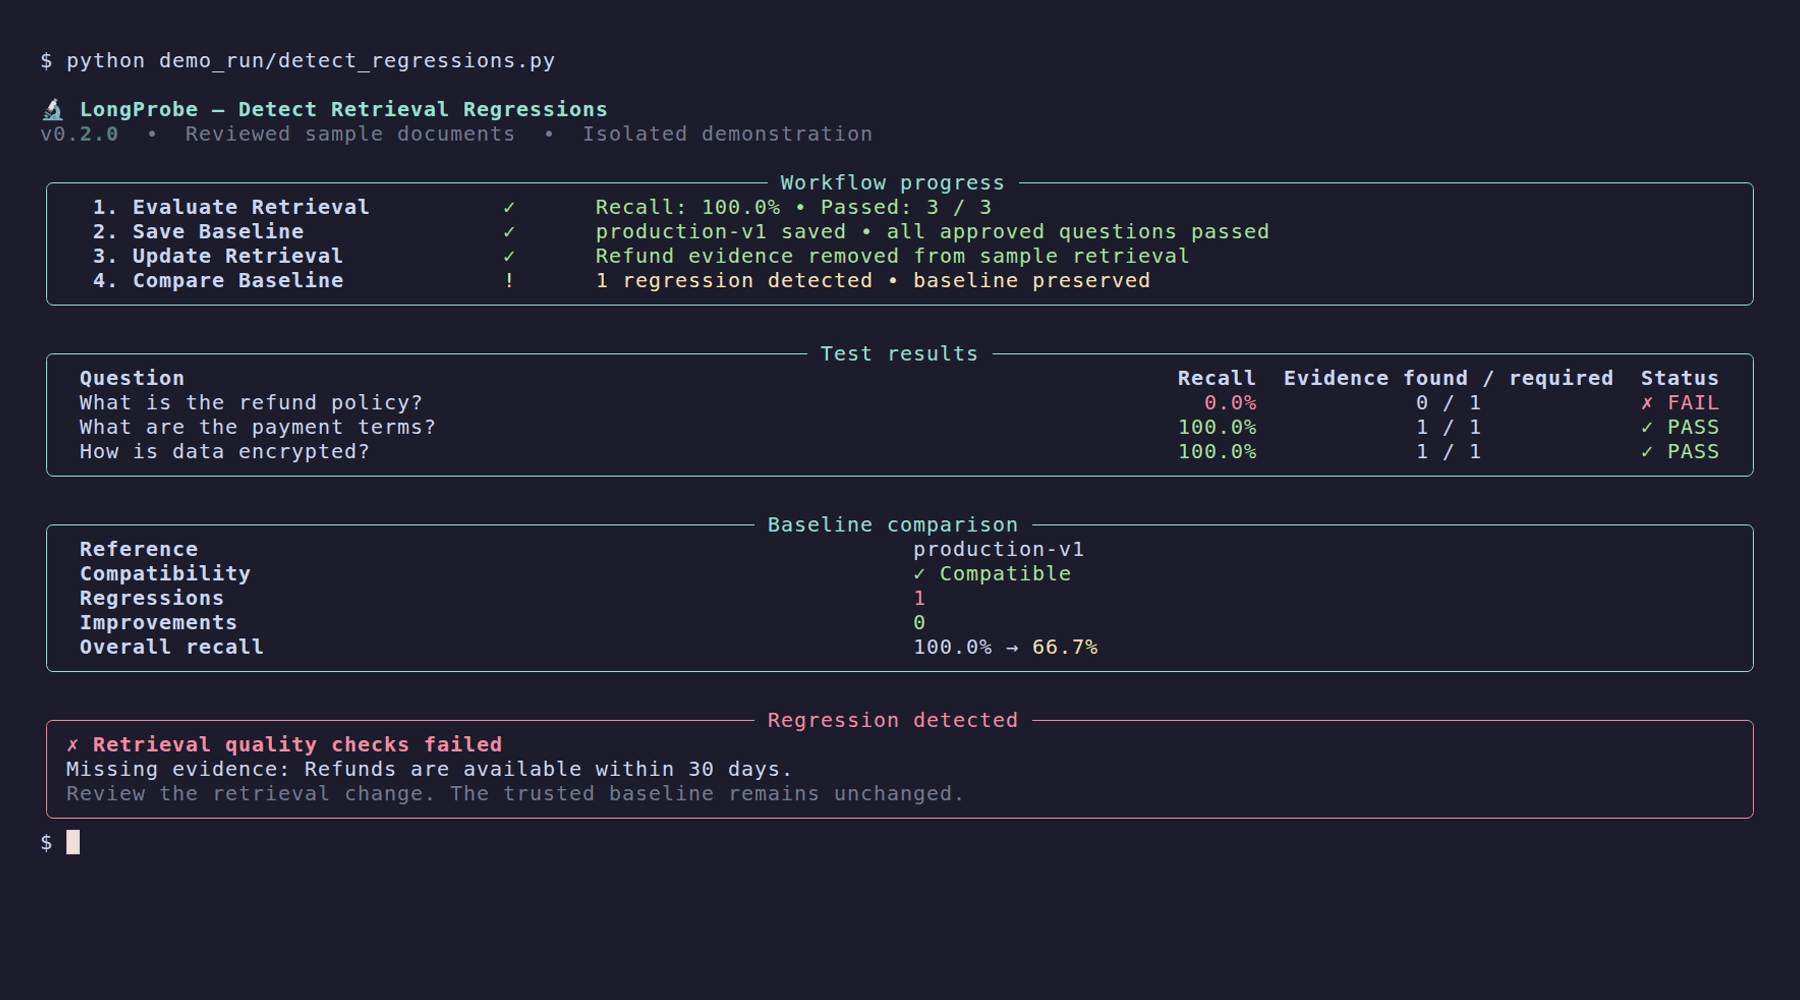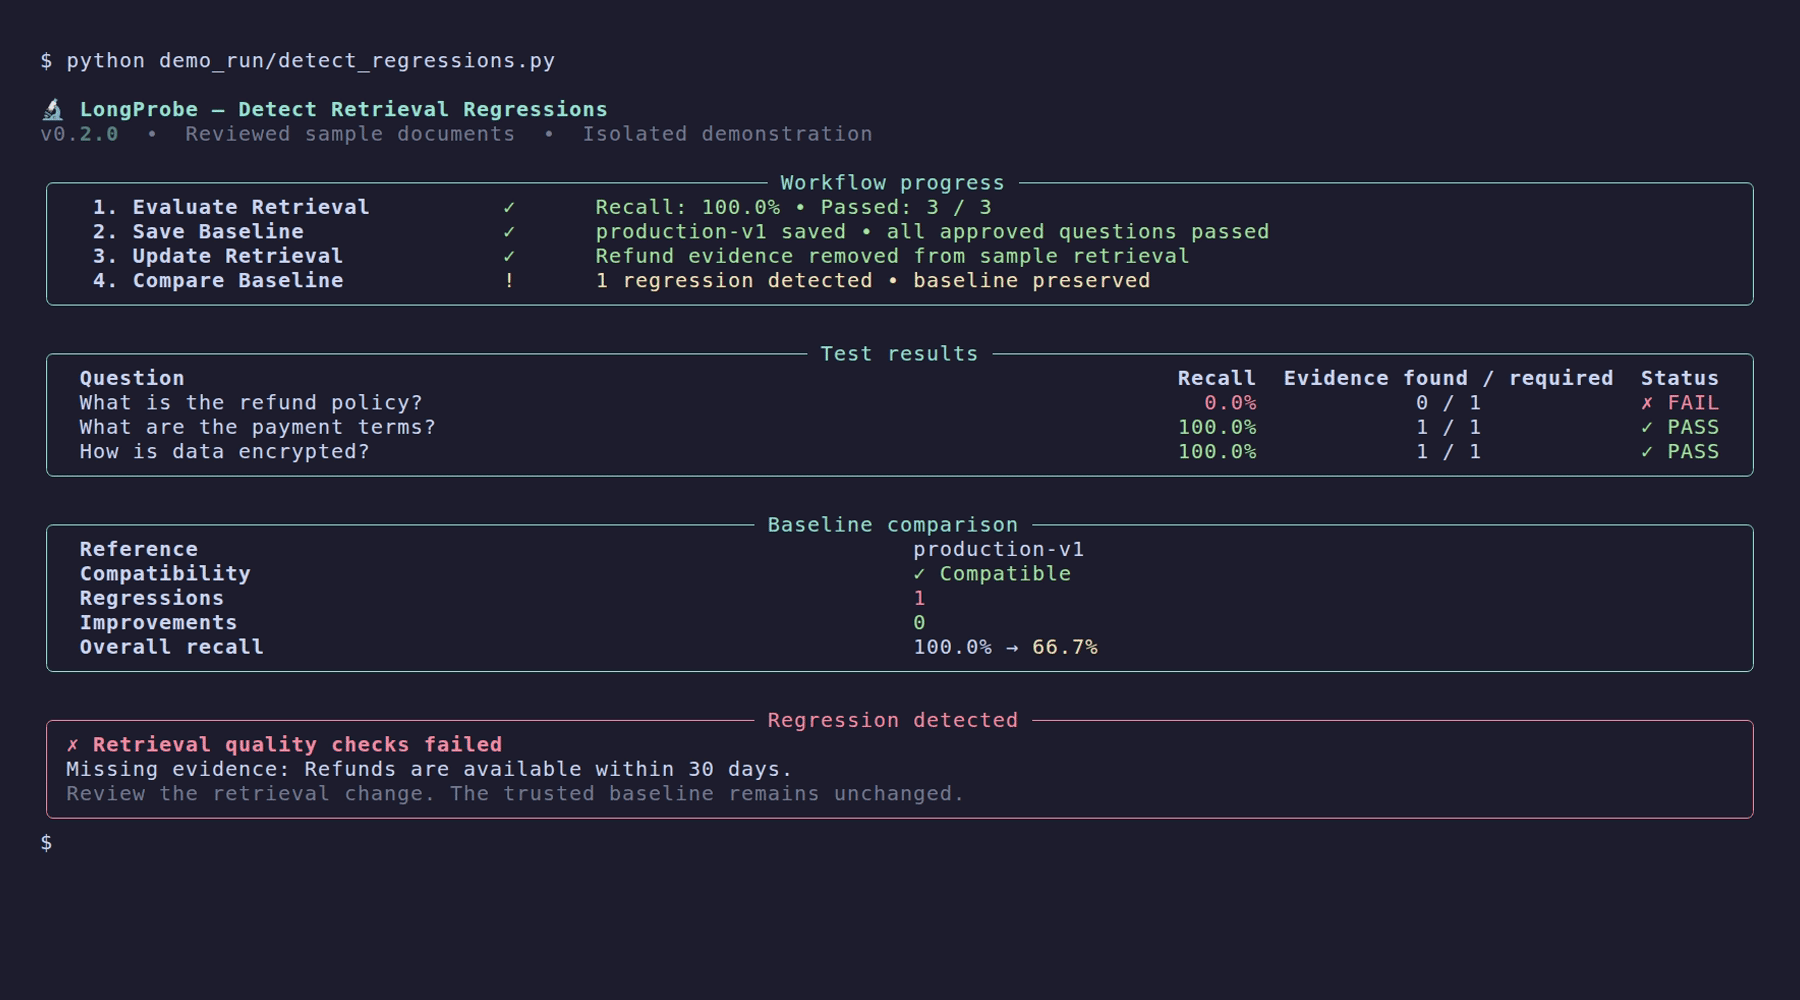
The v0.2.0 dashboard scenario explicitly selects a baseline and displays compatibility, regression/improvement counts, lost evidence, and the shared quality verdict. A retrieval check does not establish overall deployment readiness.
Run locally
From the repository root:
The deterministic sample retriever starts with all three reviewed cases passing. The script saves an eligible reference, removes refund evidence, and evaluates again. It shows one regression, zero improvements, compatible contracts, and failed quality. Temporary files are removed afterward; no external database or embedding model is required.
Python workflow
# probe is configured with your adapter and reviewed golden suite.
report = probe.run()
probe.save_baseline(label="production-v1")

# After an application retrieval change:
report2 = probe.run(baseline_label="production-v1")
diff = report2.comparison
print(f"Compatible: {diff['compatible']}")
print(f"Regressions: {len(diff['regressions'])}")
print(f"Improvements: {len(diff['improvements'])}")
assert report2.quality["passed"], report2.quality["reasons"]
The assertion fails if a selected question fails, evidence regresses, or a comparison is incompatible. Zero regressions alone is insufficient to establish passing quality. Missing explicit references fail before retrieval.
CLI equivalent
With a working application retriever and reviewed golden questions:
longprobe baseline save --label production-v1
longprobe baseline list
longprobe check --baseline production-v1
longprobe diff --baseline production-v1
The last two commands are alternatives for a live comparison; each performs its own evaluation. A check never replaces the saved reference automatically. Changed coverage or evaluation contracts require review before intentionally establishing a new reference.
See baseline management and the CLI reference. Regenerate the GIF with make demos using the prerequisites in demos/README.md.