Complete Workflow
Follow a retrieval change from reviewed golden questions to a saved baseline and a detected regression. This demonstration shows which question failed, what evidence disappeared, and why the quality check failed.
Demo
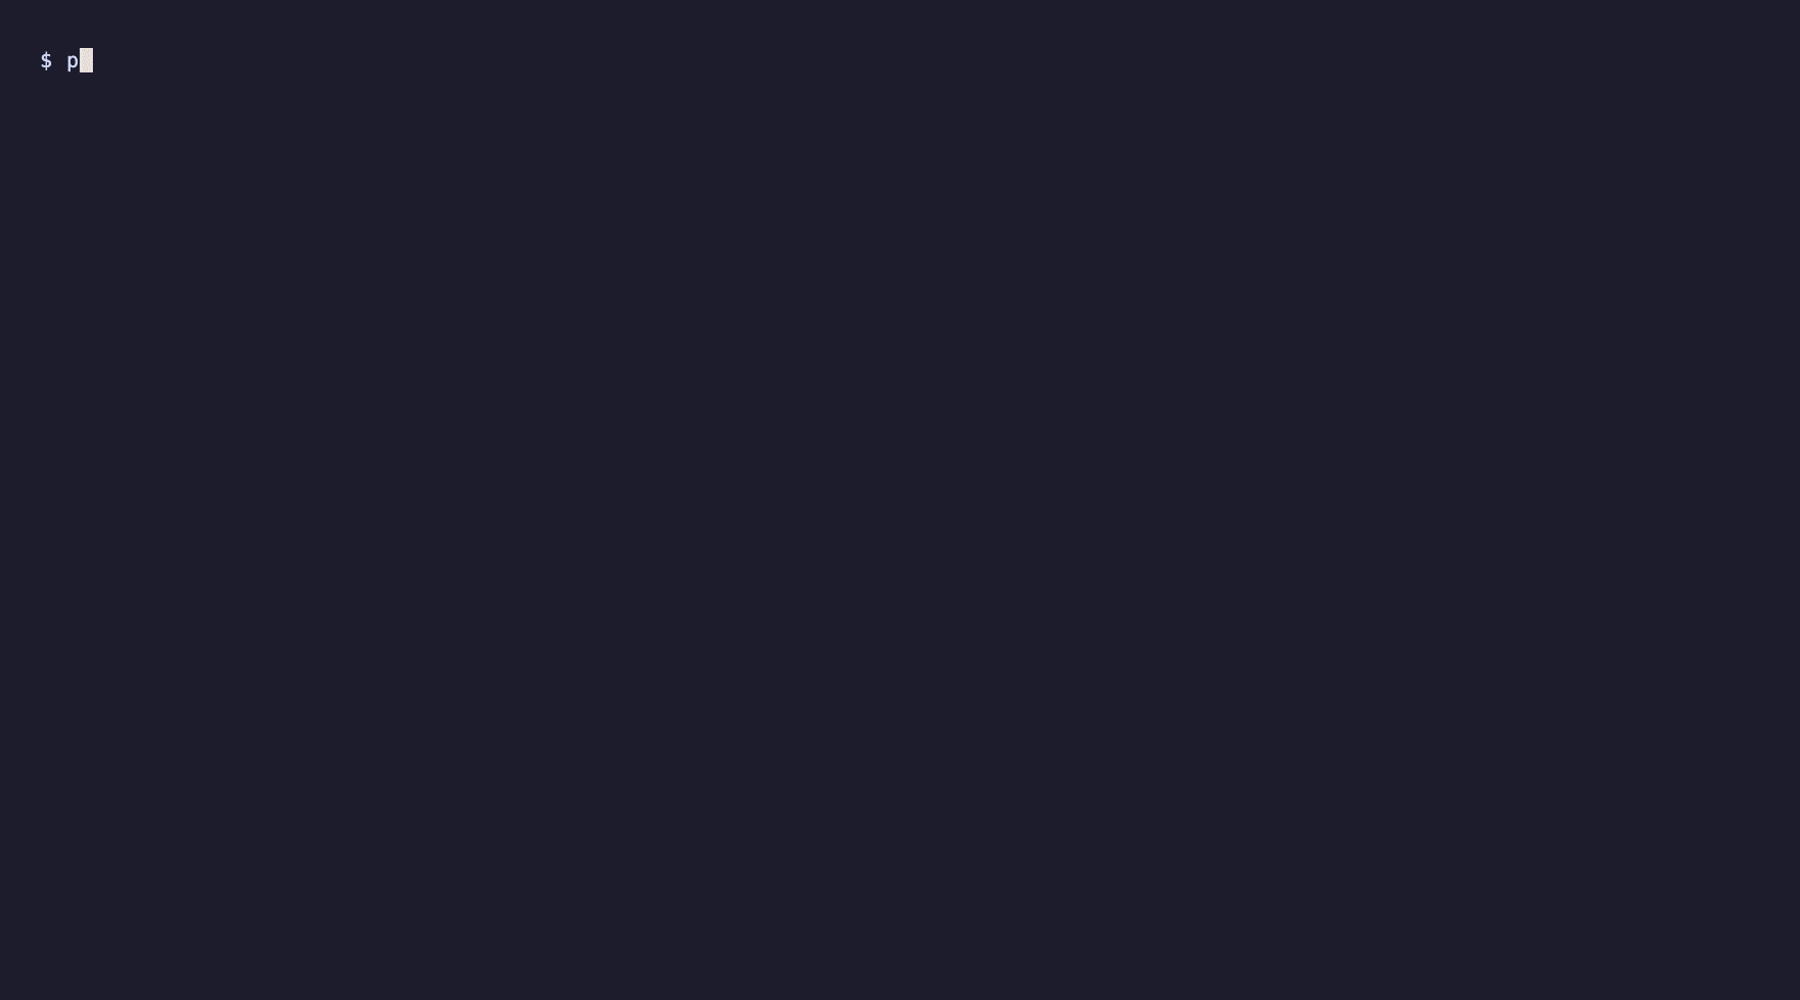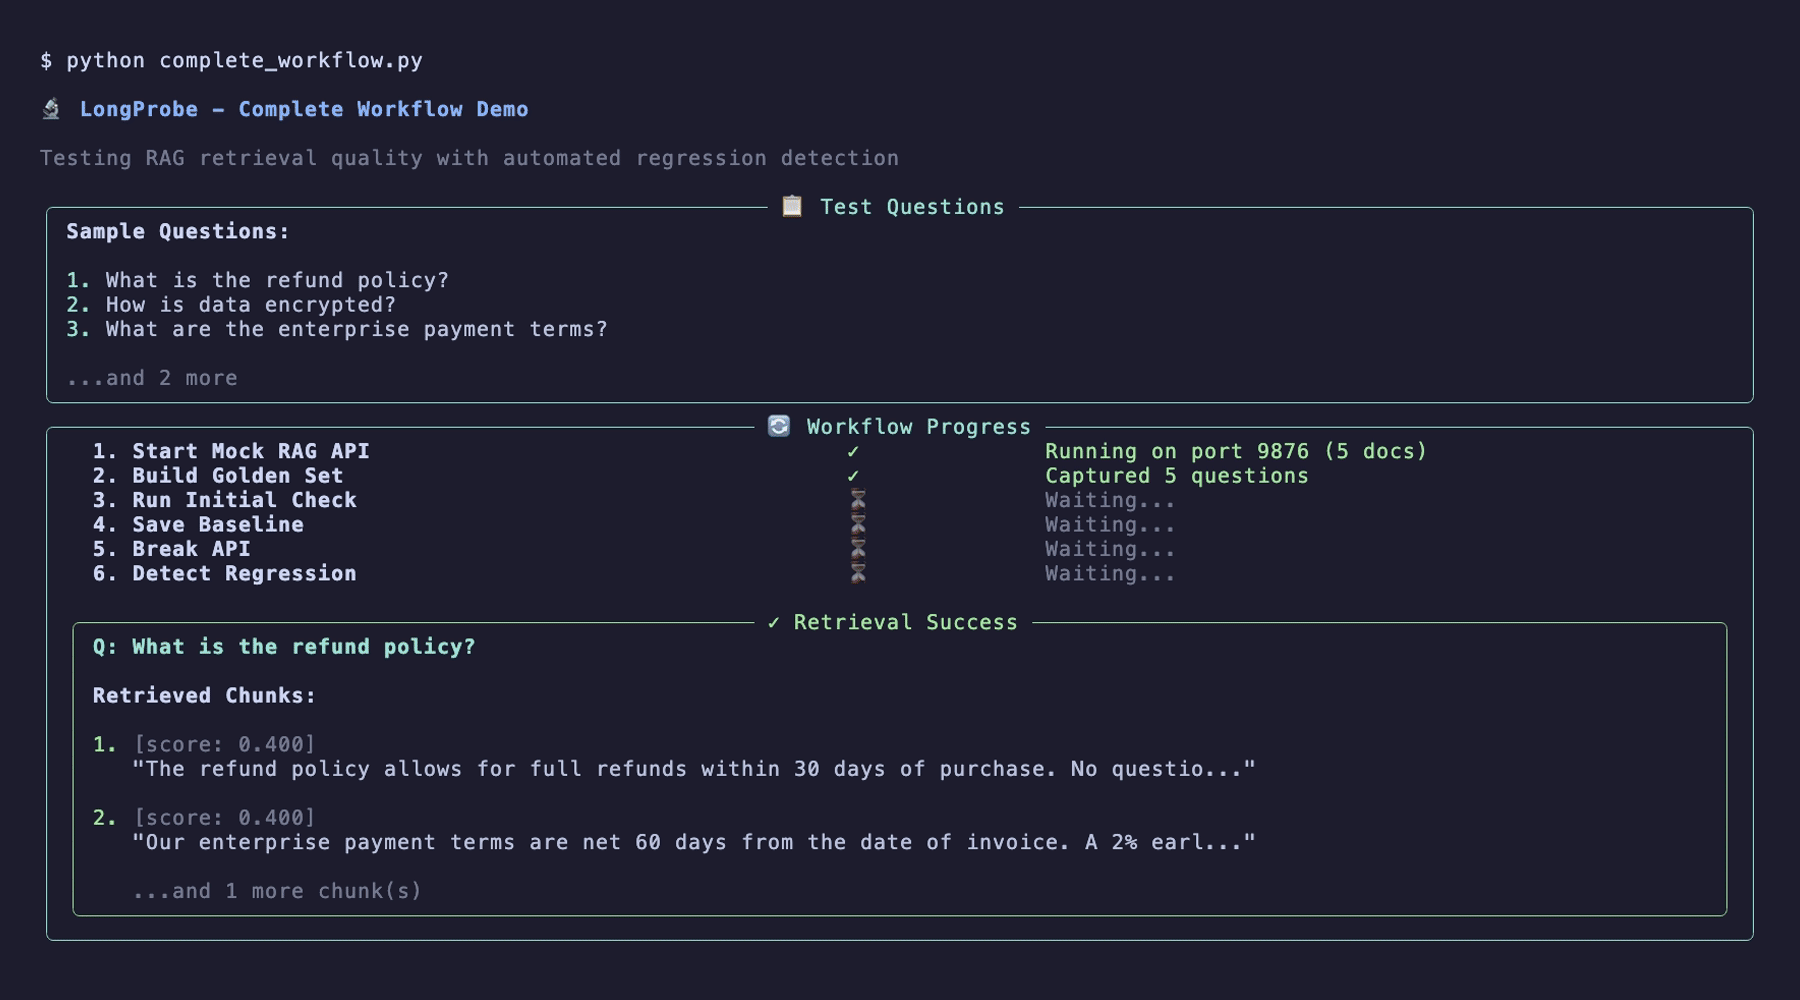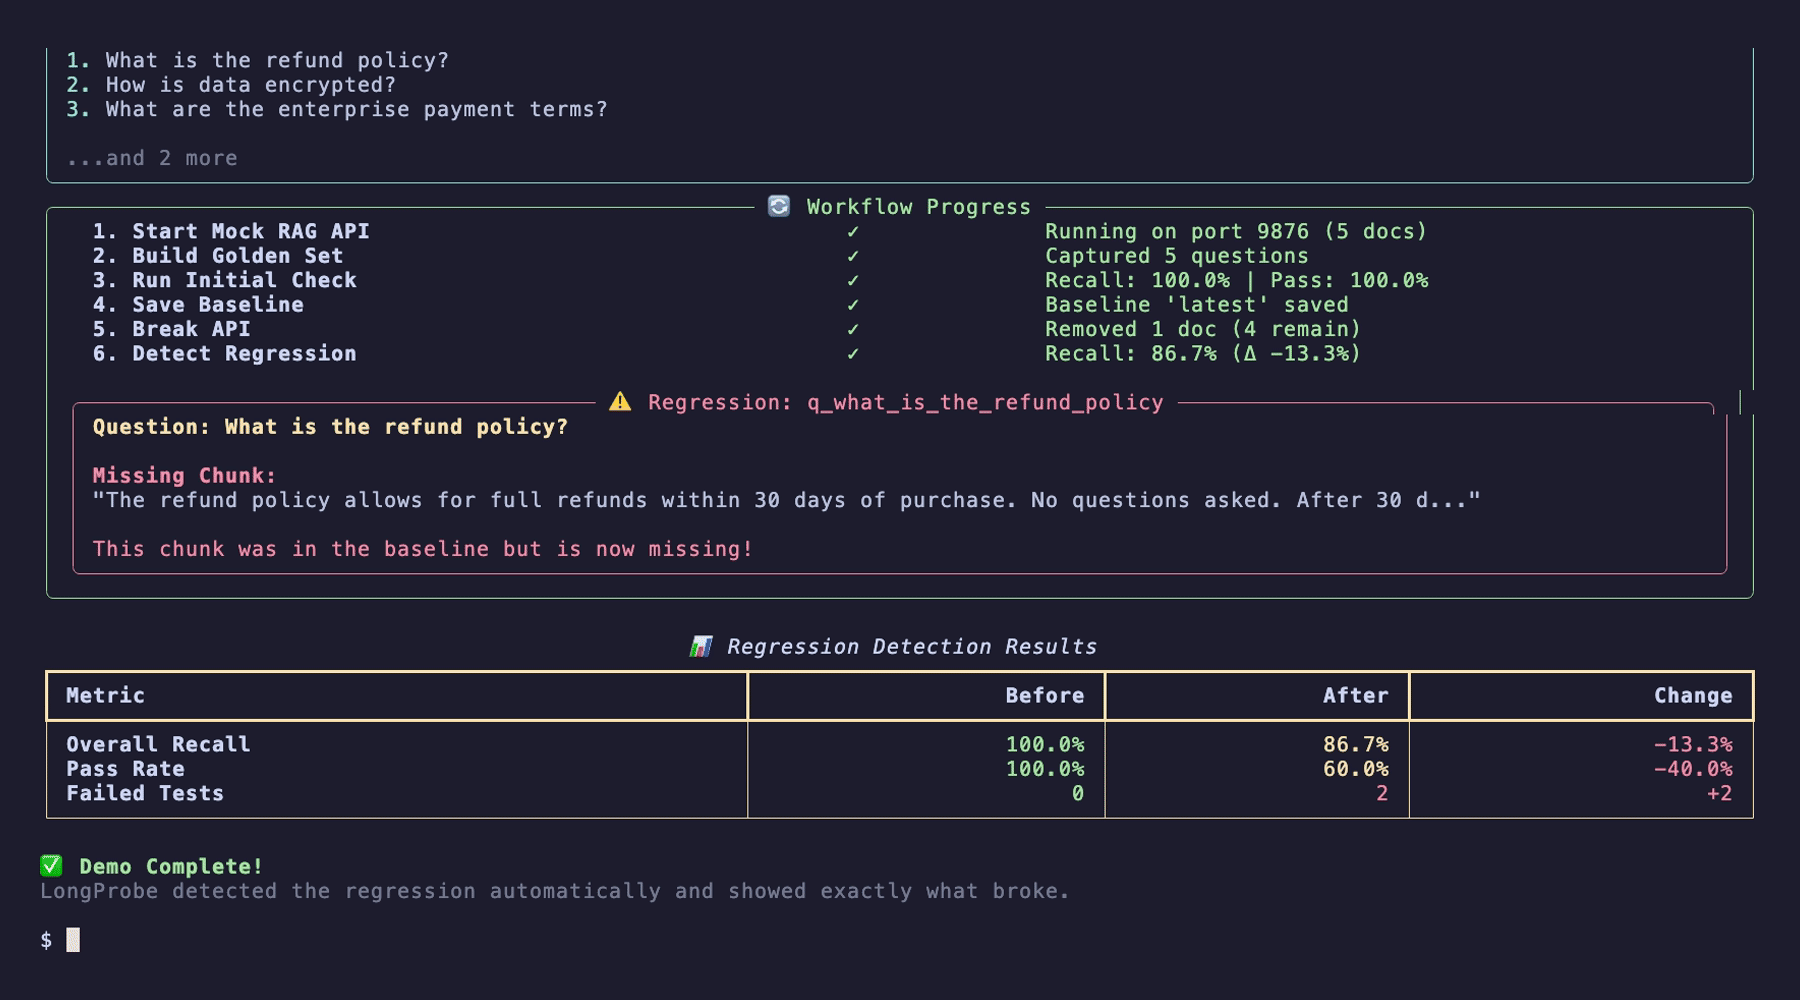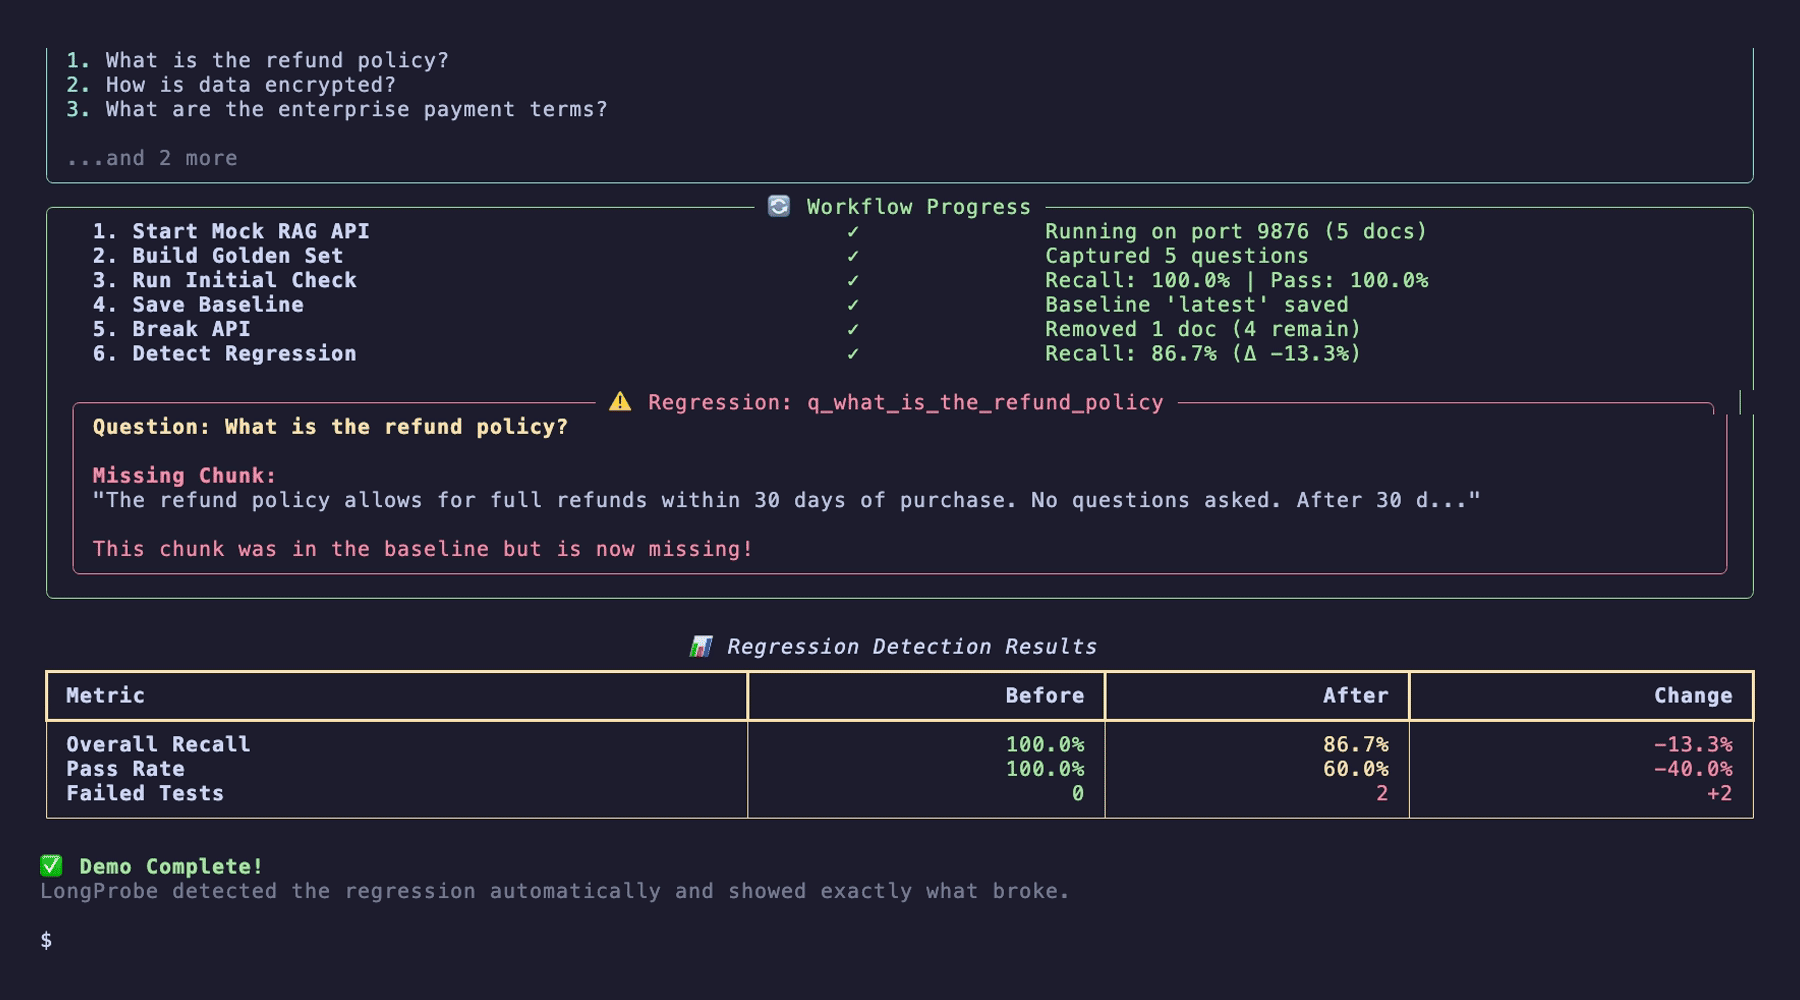
The dashboard uses animated progress panels, color-coded results, and a before-and-after comparison. It displays no Python source code. The GIF plays at twice the original recording speed.
Overview
The demo tests three questions about refund policy, payment terms, and encryption. All three initially pass. After the sample retriever stops returning refund evidence, LongProbe detects one regression while the other two questions continue to pass.
It uses fixed sample documents and an in-memory retriever to exercise real LongProbe evaluation, comparison, and SQLite baseline promotion. No external API, vector database, embedding model, or credentials are needed. The sample is a retrieval regression demonstration; it does not evaluate generated answers or establish overall deployment readiness.
What You Will Learn
- How draft questions become reviewed, approved test cases.
- How recall percentages relate to required evidence.
- When a report is eligible to become a trusted baseline.
- How to select a reference explicitly and identify lost evidence.
- Why a failed check should leave the trusted reference unchanged.
Workflow Steps
1. Prepare Golden Questions
Prepare three candidate questions with expected evidence and draft status. Drafts are excluded from ordinary checks until approved.
In your own project, write candidates manually or use capture or generate --auto-capture. Retrieved evidence is a candidate requirement: the retriever may already be returning incomplete or incorrect results.
2. Review and Approve Evidence
Check each question and required evidence item against its source document before changing its status to approved.
The recording displays the sample source evidence and illustrates approval using fixed, pre-reviewed fixtures. It does not perform human review or provide a separate approval system. In a real project, a person makes that review decision.
3. Run the Initial Evaluation
Evaluate the approved questions using an 85% recall threshold. The dashboard shows each question's recall, evidence found / required, and PASS/FAIL result.
All three sample questions initially find their required evidence. Overall recall and pass rate are both 100%.
4. Save a Trusted Baseline
Explicitly save the eligible report as production-v1. Under the default all_questions promotion policy, every evaluated approved question must pass. A good average cannot compensate for a failing question.
A passing check does not save a reference automatically. Python promotion reuses the retained evaluation snapshot; the CLI baseline save command performs a fresh evaluation.
5. Simulate a Retrieval Change
Remove refund evidence from the sample retriever while keeping the reviewed golden requirements unchanged.
This illustrates a failure that could follow an index update, document removal, or change to your retrieval pipeline. Keeping the requirements unchanged allows LongProbe to compare the same expectations before and after the change.
6. Detect and Explain the Regression
Evaluate again with production-v1 explicitly selected. The reports have compatible evaluation contracts, so LongProbe can identify the lost refund evidence and report a regression.
The final dashboard shows one failed question, one regression, zero improvements, and a failed quality verdict. The trusted baseline remains unchanged for investigation and recovery.
Before-and-After Results
| Metric | Initial evaluation | After refund evidence is removed |
|---|---|---|
| Overall recall | 100.0% | 66.7% |
| Pass rate | 100.0% | 66.7% |
| Passing questions | 3 of 3 | 2 of 3 |
| Failing questions | 0 | 1 |
| Quality verdict | PASS | FAIL |
| Historical comparison | No reference exists yet | Compatible with production-v1 |
| Regressions / improvements | Not applicable | 1 / 0 |
Each sample question requires one evidence item:
| Result | Recall | Evidence found / required | Status |
|---|---|---|---|
| Required evidence returned | 100.0% | 1 / 1 | PASS |
| Required evidence missing | 0.0% | 0 / 1 | FAIL |
Recall measures required evidence found. A retriever's similarity score is a different measurement and is not a correctness percentage. This synthetic demo does not display similarity scores.
Run Locally
From the repository root containing pyproject.toml:
For a run without presentation pauses:
Setup requires Python 3.11 or newer and may download package dependencies. Once installed, the scenario runs without external services. It creates temporary golden, configuration, and baseline files, then removes them afterward.
The script verifies that the deliberate regression is detected and exits successfully when the demonstration behaves as expected. Its successful exit does not mean the second retrieval evaluation passed. To regenerate the GIFs, follow demos/README.md.
Python API Example
For your application, supply its configured retriever adapter, reviewed golden suite, and scoring configuration. The example assumes those files and the adapter object already exist; set scoring.recall_threshold: 0.85 in longprobe.yaml to match the demo.
from longprobe import LongProbe

probe = LongProbe(
    adapter=adapter,
    goldens_path="goldens.yaml",
    config_path="longprobe.yaml",
)

# Evaluate the reviewed suite and explicitly promote an eligible reference.
report = probe.run()
assert report.quality["passed"], report.quality["reasons"]
probe.save_baseline(label="production-v1")

# After changing your application's retrieval pipeline:
report2 = probe.run(baseline_label="production-v1")
diff = report2.comparison
print(f"Compatible: {diff['compatible']}")
print(f"Regressions: {len(diff['regressions'])}")
print(f"Improvements: {len(diff['improvements'])}")
assert report2.quality["passed"], report2.quality["reasons"]
The final assertion fails for the deliberate missing-evidence scenario. It also catches individual question failures and incompatible comparisons. The recording shows that verdict through its dashboard without displaying code or a traceback.
CLI Workflow for Your Application
Configure a working application retriever in longprobe.yaml before using these commands. This workflow operates on your application's data, rather than the recording's temporary fixtures.
# Capture a candidate question and evidence as a draft.
longprobe capture --question "What is the refund policy?" --auto

# Review the question and source evidence before approving it.
longprobe edit

# Inspect approved-question quality before establishing a reference.
longprobe check --no-compare
longprobe baseline save --label production-v1

# After changing your application's retrieval pipeline:
longprobe check --baseline production-v1
Inspect required evidence in YAML when needed; the editor does not expose every field. longprobe diff --baseline production-v1 is another way to run a live comparison. Each live command performs its own evaluation.
Intentional changes to question coverage or evaluation contracts can make strict comparison incompatible. Review those changes and explicitly establish a new reference when appropriate; do not replace expected evidence simply to make a failing check pass.
Next Steps
- Golden Questions — create, review, and maintain expected evidence.
- Monitor RAG Quality — inspect individual results and the shared verdict.
- Detect Retrieval Regressions — compare against a selected reference.
- Baseline Management — understand promotion, compatibility, and migration.
- Python API — connect your application's retriever.